EXP-001Runs recordedWeb app

AI Travel Planner

Three coding agents, one 1,245-line product spec, eight hours each. Build a real AI travel SaaS and deploy it.

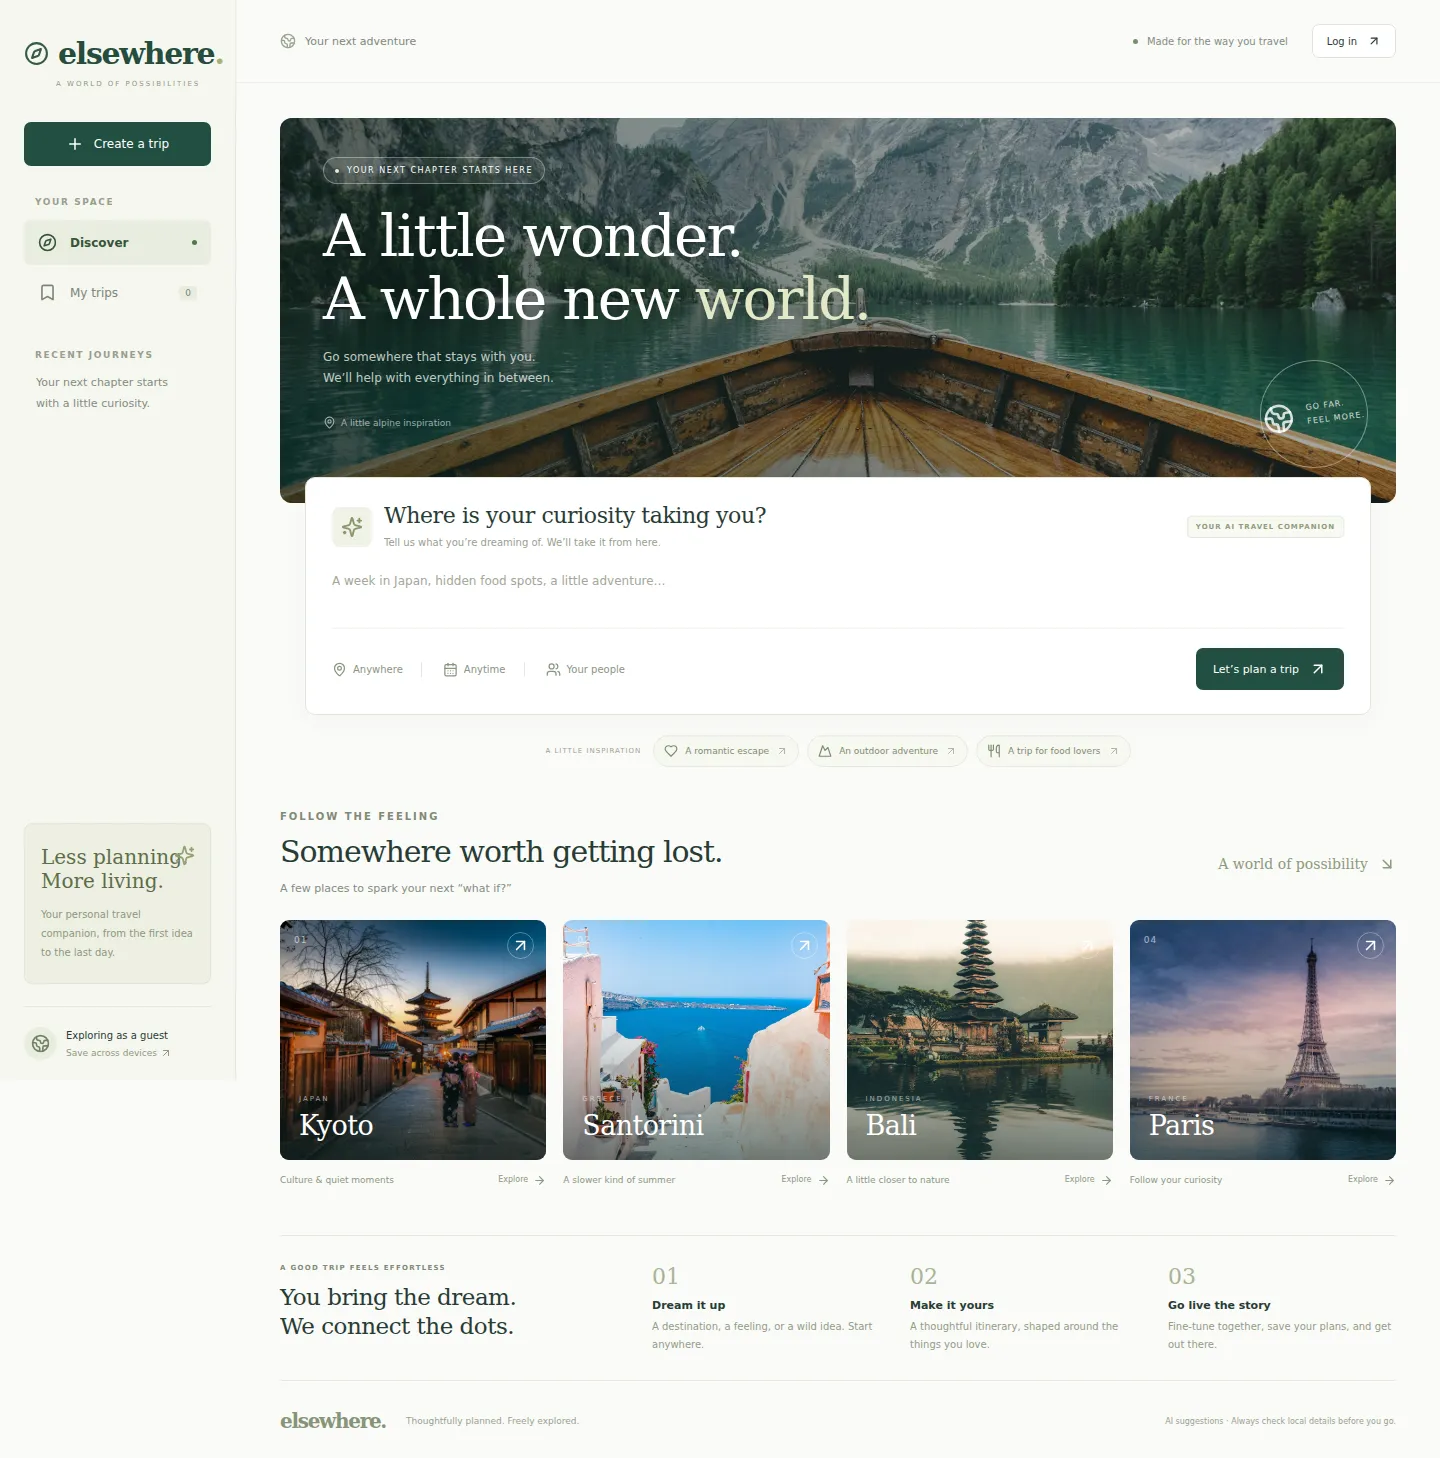
Discover screen of the Codex-built travel planner, "Elsewhere", from a screenshot the agent committed
Time budget
8h per agent
Spec
v1.7 committed Nov 4, 2026
Agents
3 3 runs recorded
Runs recorded
Nov 5, 2026
Evaluation
Pending

01 The hypothesis

The hypothesis

Given a serious, production-style product spec and an eight-hour window, an AI coding agent can deliver a deployed, end-to-end working SaaS application on its own, not just a convincing demo.

Questions this experiment asks

  1. Does the deployed app actually work end to end, or does it only look finished?
  2. How much human intervention or approval does each agent need?
  3. How do the agents handle real integrations such as LLMs, Google Places, email and CI deploys?
  4. How honest are the agents' own build reports about what they verified?

Why a travel planner?

A travel planner sounds simple until you write the spec. This one asks for a conversational AI that edits structured itineraries without trashing unrelated days. It also needs real place data rather than invented opening hours, guest sessions that migrate into accounts, email verification, an admin console with its own identity system, and per-request cost accounting for every LLM and Google Places call. All of it has to be deployed through a CI pipeline the agent didn’t build.

That makes it a good first test. Polished screenshots are easy to produce, and you can’t fake the integrations.

How the runs were set up

Each agent got its own GitHub repository, holding the license and spec v1.7 before the run started. Each had its own Cloudflare Worker, connected to its repository through Workers Builds, and the same runtime model (gpt-4o-mini) set by the administrator. The runs took place one after another on 5 November 2026 and were screen-recorded.

What we know so far

The runs are recorded and the repositories are public. Each agent left a BUILD_REPORT.md and a machine-readable BUILD_RESULTS.json. What follows on this page comes from those artifacts and the git history, and is labeled that way. Agent claims are not verified results. The independent evaluation, with hands-on testing of each deployed app, comes next and will be published alongside the episode.

02 The rules

The challenge, as specified

A modern AI travel planner that feels like a polished consumer SaaS product, not a technical prototype. Users describe a trip in plain language, get a personalized day-by-day itinerary, refine it in conversation and save it. A separate admin interface covers user management, trip inspection, API usage monitoring and cost reporting.

Required scope Spec: A requirement from the versioned specification.

  • Conversational itinerary generation and editing that keeps context and separates verified facts from estimates
  • Structured day-by-day itineraries stored as data and shown in dedicated UI, not just chat text
  • Guest access, plus registered accounts with email verification and password recovery
  • Destination research through real APIs (Google Places), with no fabricated prices or opening hours
  • Interactive map of itinerary locations by day
  • Separate admin dashboard with a forced first-login password change, and user and trip inspection
  • Per-request LLM and Google Places cost tracking, date-filtered reporting and an append-only audit log
  • Runtime-configured LLM provider and model behind a provider abstraction

Constraints Spec: A requirement from the versioned specification.

  • Eight-hour delivery window per agent, measured in wall-clock time
  • Make routine decisions independently; do not wait for plan approval
  • No project-specific agent instruction files (CLAUDE.md, AGENTS.md, .cursor/rules)
  • Do not bypass approval mechanisms; request approval when an operation requires it
  • Do not create, replace or read production secrets
  • All hosting and persistence on Cloudflare; deploy through the existing GitHub-connected Workers Builds pipeline
  • Do not claim tests passed unless they actually ran successfully

Deliverables Spec: A requirement from the versioned specification.

  • Application source, migrations, infrastructure config and automated tests
  • GitHub-connected production deployment
  • README.md and a progress log
  • BUILD_REPORT.md with a requirement-by-requirement status table
  • BUILD_RESULTS.json, machine-readable results for independent evaluation
  • The application should feel like a polished consumer SaaS product rather than a technical prototype.spec v1.7
  • Code existing in the repository alone is not proof that a feature works.spec v1.7
  • Do not claim tests passed unless they were actually executed successfully.spec v1.7

03 The contenders

Three agents, three attempts

  • Claude CodeAnthropicRun completed

    App name: AI Travel Planner

    A Hono + React app on a reused Worker with D1. It has a chat workspace with itinerary, map and explore views, a seven-section admin console, and a global daily cost cap. The agent tested in production against real OpenAI, Places and email, and reports reading real verification emails through a disposable inbox.

    Run length Agent claim: Reported by the agent in its own build report. Not independently verified.
    1h 25m
    Demo
    Demo not public
    Full run report
  • OpenAI CodexOpenAIRun completed

    App name: Elsewhere

    A plain Worker (no framework) with D1 and a React 19 front end, branded "Elsewhere". It has a Discover home screen, structured trip cards with optimistic concurrency, and a separate admin app with drill-downs. It committed the most evidence of the three runs, including screenshots and JSON check logs.

    Run length Agent claim: Reported by the agent in its own build report. Not independently verified.
    1h 28m
    Demo
    Demo not public
    Full run report
  • Cursor CLICursorRun completed

    App name: AI Travel Planner

    A Hono + React app on a reused Worker with D1, plus KV for rate limits. It has a conversational planner with an itinerary panel and Leaflet map, and an admin area with metrics and audit views. It was the fastest run by far (about 24.5 minutes self-reported), with the smallest test suite and several items it marked unverified.

    Run length Agent claim: Reported by the agent in its own build report. Not independently verified.
    24.5 min
    Demo
    Demo not public
    Full run report

04 Build timeline

Minute by minute, from each agent's own start

Commits come from the public git history. Start and end times, problems and fixes come from the agents' own reports. The runs took place at different times on Nov 5, 2026, so each lane starts at zero.

  • Commit
  • Problem
  • Fix
  • Deploy
  • Start / end
View the timeline as a table

Claude Code, started 22:28 UTC

OffsetTimeEventTypeSource
+0 min22:28 UTCRun startedStartAgent claim: Reported by the agent in its own build report. Not independently verified.
+2 min22:30 UTC ≈Found the existing DB binding pointed at a missing database, so created a new D1 databaseProblemAgent claim: Reported by the agent in its own build report. Not independently verified.
+42 min23:10 UTCImplement AI Travel Planner on Cloudflare Workers and D1CommitGit record: Taken from the public repository's commit history.
+50 min23:18 UTCClose guest quota gap, handle over-long trips, add browser journeysCommitGit record: Taken from the public repository's commit history.
+54 min23:22 UTCAllow the zone-injected Cloudflare Web Analytics beacon in the CSPFixGit record: Taken from the public repository's commit history.
+1h 4m23:31 UTCFix source badge on stops without a place; add README and production checksFixGit record: Taken from the public repository's commit history.
+1h 9m23:37 UTCOnly open the map when the traveler asksFixGit record: Taken from the public repository's commit history.
+1h 15m23:43 UTCStop rejecting correct Places matches because of bad model coordinatesFixGit record: Taken from the public repository's commit history.
+1h 25m23:53 UTCBuild report generatedEndAgent claim: Reported by the agent in its own build report. Not independently verified.
+1h 26m23:53 UTCAdd build report artifacts and a test for the daily cleanup jobCommitGit record: Taken from the public repository's commit history.

OpenAI Codex, started 16:36 UTC

OffsetTimeEventTypeSource
+0 min16:36 UTCRun startedStartAgent claim: Reported by the agent in its own build report. Not independently verified.
+33 min17:08 UTCImplement Elsewhere travel planner with secure Cloudflare backend and reportingCommitGit record: Taken from the public repository's commit history.
+33 min17:09 UTC ≈First Workers Build failed at npm ci (lockfile missing a peer entry)ProblemAgent claim: Reported by the agent in its own build report. Not independently verified.
+42 min17:17 UTCFix Cloudflare npm lock compatibility and verify responsive travel workspaceFixGit record: Taken from the public repository's commit history.
+44 min17:20 UTCFirst production smoke test returned HTTP 500 on admin login (PBKDF2 iteration limit)ProblemAgent claim: Reported by the agent in its own build report. Not independently verified.
+47 min17:22 UTCRetain full-strength password hashing on Cloudflare production runtimeFixGit record: Taken from the public repository's commit history.
+1h 4m17:40 UTCComplete production verification, reporting drill-downs and build handoffCommitGit record: Taken from the public repository's commit history.
+1h 10m17:45 UTCApply security headers to Cloudflare-served HTMLFixGit record: Taken from the public repository's commit history.
+1h 17m17:52 UTCAccount for deleted-trip usage in unattributed costsFixGit record: Taken from the public repository's commit history.
+1h 28m18:03 UTCBuild results generatedEndAgent claim: Reported by the agent in its own build report. Not independently verified.
+1h 28m18:04 UTCPublish final build reports and verified deployment handoffCommitGit record: Taken from the public repository's commit history.

Cursor CLI, started 19:01 UTC (approximate)

OffsetTimeEventTypeSource
+0 min19:01 UTC ≈Run started (approximate)StartAgent claim: Reported by the agent in its own build report. Not independently verified.
+19 min19:20 UTCImplement AI Travel Planner v1 on Cloudflare WorkersCommitGit record: Taken from the public repository's commit history.
+21 min19:22 UTCFix Workers Builds npm peer dependency resolutionFixGit record: Taken from the public repository's commit history.
+23 min19:23 UTCTrigger Workers Builds after configuring npm run buildDeployGit record: Taken from the public repository's commit history.
+25 min19:25 UTCRun endedEndAgent claim: Reported by the agent in its own build report. Not independently verified.
+25 min19:25 UTCUpdate build reports after verified GitHub Workers Builds successCommitGit record: Taken from the public repository's commit history.

05 What they built

Features claimed, and gaps admitted

Both lists come from each agent's own build report. Highlights are what the agent says it built. Gaps are what it marked as partial, unverified or missing.

Claude CodeAgent claim: Reported by the agent in its own build report. Not independently verified.

Highlights

  • AI edits are applied on the server as a list of operations, so unrelated itinerary content can't change
  • Itinerary stops carry source badges (verified place or AI suggestion) and warnings for overlaps and closed venues
  • Map with numbered, day-colored pins, and dashed pins for unverified locations
  • Admin console with Overview charts, Users, Trips, Usage and costs, Operations, Administrators and an Audit log
  • Per-owner, per-address and daily limits, plus a global daily estimated-cost cap
  • Replaced the default admin password in production about two minutes after the first deploy

Gaps it reported

  • Schedule practicality is Partial (depends on the model and was not systematically assessed)
  • Accessibility marked Implemented but Unverified (no screen-reader test or automated audit)
  • Long-distance drag reorder failed under Playwright, and touch drag was not implemented
  • Some failure paths, rate limits and the cost cap were tested only with mocks
OpenAI CodexAgent claim: Reported by the agent in its own build report. Not independently verified.

Highlights

  • Optimistic concurrency on trips (revision numbers), with overlapping schedules rejected
  • The server preserves unrelated days during single-day conversational edits
  • Configurable pricing with stored price snapshots, and unknown prices recorded as null instead of guessed
  • Kept full-strength 600,000-iteration password hashing on Cloudflare by switching libraries rather than lowering the work factor
  • Found that static HTML was missing security headers and fixed it with a _headers file, then re-checked

Gaps it reported

  • Production end-to-end verification is Partial (inbox receipt, link consumption and multi-device access not run)
  • Real inbox receipt of verification and reset emails was blocked, because there was no controlled mailbox
  • Map lines show order, not routed directions; destination photos are decorative stock images
  • No automatic retries on LLM calls, by design, to avoid duplicate billing
Cursor CLIAgent claim: Reported by the agent in its own build report. Not independently verified.

Highlights

  • Guest cookie backed by a hashed server-side token, with trips and usage migrated into an account
  • KV-based rate limits on auth, chat and places endpoints
  • Per-request usage records with versioned pricing
  • Admin area with a forced bootstrap password change, UTC date presets, audit views and bar charts

Gaps it reported

  • Itinerary editing is Partial (one chat edit returned no structured update)
  • Email verification and recovery are Partial (inbox delivery not confirmed)
  • Secrets discipline is Partial (the first deploy cleared administrator-managed variables, which were then restored)
  • Destination research, polished UI and audit logging are marked Implemented but Unverified
  • No browser or end-to-end tests reported

Screenshots committed by the agents

Only the OpenAI Codex run committed screenshots to its repository. Other agents' UIs will be shown after hands-on evaluation, rather than borrowed from marketing-style captures.

06 Head-to-head evaluation

Evaluation pending

Independent testing and scoring have not been published yet. Every metric on this page comes from the agents' own reports or from git history, and has not been verified.

Side-by-side comparison of agent runs. Every row shows where its data comes from.
MetricClaude CodeAnthropicOpenAI CodexOpenAICursor CLICursor
Run lengthAgent claim: Reported by the agent in its own build report. Not independently verified.Elapsed time the agent recorded in BUILD_RESULTS.json.1h 25m5,125 seconds, measured until the report was generated. The final commit and build check came after.1h 28m5,262 seconds, measured when the report was generated. The end time was left empty on purpose while publishing was still in progress.24.5 min1,470 seconds. The start time is given as approximate ("~19:01 UTC").
Approval behaviorObserved: Observed by The Build Hypothesis during the recorded run.What we saw during the recorded session.Ran through without asking for further input during the run.Asked for approval whenever it needed to run a new command. Commands it had already been allowed could be allowed again.Asked for approval once and offered a "run everything" option, which was selected.
Human interventionsAgent claim: Reported by the agent in its own build report. Not independently verified.Each agent defined "intervention" differently.None reported ("No human interventions occurred.")Counts tool approvals as interventions (dependency installs, Cloudflare provisioning and migrations, test runtime). No manual code changes."None required beyond tool permissions."
Requirements trackedAgent claim: Reported by the agent in its own build report. Not independently verified.Each agent split the spec into its own list, so these totals are not comparable.
73
  • 71 Verified (per agent)
  • 1 Implemented but unverified
  • 1 Partial
The agent split the spec into 73 requirements.
55
  • 54 Verified (per agent)
  • 1 Partial
The agent says "Verified" often means a local test with mocked services, not production verification.
24
  • 19 Verified (per agent)
  • 3 Implemented but unverified
  • 2 Partial
BUILD_RESULTS.json lists 24 requirements. The Markdown report's table has 27 rows (19 Verified, 5 Unverified, 3 Partial).
Automated testsAgent claim: Reported by the agent in its own build report. Not independently verified.Suites differ in scope (unit, browser, production smoke).
  • 236✓Unit and integration (Vitest in workerd, real D1, mocked external APIs)
  • 9✓ 1 skippedProduction browser tests (Playwright, real OpenAI, Places and email)
  • 13✓Production admin bootstrap activation
  • 20✓Production walkthrough (spec §14.5)
  • 39✓Worker API tests (Vitest in workerd, local D1, mocked externals)
  • 8✓Local browser tests (Playwright, desktop and mobile)
  • 8✓Production browser tests
  • 16✓Production admin browser checks
  • 22✓Production smoke checks (real OpenAI, Google and email binding)
  • 24✓Production bootstrap smoke
  • 15✓Unit tests (Vitest, local)
  • 6✓Production checks (health, config, guest itinerary, register and migrate, admin bootstrap, forgot password)
DeploymentAgent claim: Reported by the agent in its own build report. Not independently verified.Deployed through GitHub-connected Workers Builds, with the build verified for the deployed commit.Deployed through the GitHub-connected Workers Builds pipeline. Of 6 push builds during the run, 1 failed and 5 succeeded.Reports GitHub Workers Builds success for the deployed commit. The same executive summary also lists "GitHub Builds status to be verified post-push" as a gap.
Estimated API spend while testing in productionAgent claim: Reported by the agent in its own build report. Not independently verified.This reflects how much each agent tested in production, not the app's efficiency.$4.94Estimated from list prices for the agent's own production testing (67 LLM requests and 146 billable Places requests). About 99% of it is Places. This reflects how much the agent tested, not how efficient the app is.$0.066Estimated for the agent's own production checks (4 LLM calls and 2 Places calls).$0.078Sampled from the admin overview after smoke tests (last 7 days); an estimate.
Commits during the runGit record: Taken from the public repository's commit history.774
StackAgent claim: Reported by the agent in its own build report. Not independently verified.
  • TypeScript
  • Cloudflare Workers
  • Hono
  • Zod
  • React 19
  • React Router
  • Vite
  • Tailwind CSS 4
  • Leaflet + OpenStreetMap
  • Vitest
  • Playwright
  • TypeScript
  • Cloudflare Workers (no framework)
  • Zod
  • React 19
  • Vite 7
  • Leaflet + OpenStreetMap
  • @noble/hashes
  • Vitest
  • Playwright
  • TypeScript
  • Cloudflare Workers
  • Hono
  • Zod
  • React 19
  • React Router
  • Vite 7
  • react-leaflet + OpenStreetMap
  • Vitest
Public demoCurrent availability on this site.Demo not publicDemo not publicDemo not public
Independent scoreVerified: Confirmed by independent testing.Evaluation pending. No scores or winner have been published. This row will fill in once the hands-on testing is complete.

Delivery priorities, in order

Spec: A requirement from the versioned specification.
  1. 01Working planner
  2. 02Configured LLM
  3. 03Guest and registered users
  4. 04Secure auth and persistence
  5. 05Admin auth and account management
  6. 06Usage and cost tracking
  7. 07Admin dashboard
  8. 08Email
  9. 09Maps and research
  10. 10Responsive UI
  11. 11Automated tests
  12. 12Production deployment and verification
  • The spec lists these as delivery priorities, in order. It defines no numeric score and names no winner.
  • Requirement statuses use a fixed vocabulary: Verified, Implemented but Unverified, Partial, Failed, Not Started, Blocked.

07 Evidence

Inspect the artifacts yourself

Live deployments aren't linked: the experiment apps call billable AI and mapping APIs. Demo links will appear on each run page if public versions are published.

08 Observations & verdict

What we can say so far

  • Observed: Observed by The Build Hypothesis during the recorded run.

    All three agent runs finished in under two hours, despite the eight-hour allowance.

  • Observed: Observed by The Build Hypothesis during the recorded run.OpenAI Codex

    Codex asked for approval whenever it needed to run a new command. Commands it had already been allowed could be allowed again.

  • Observed: Observed by The Build Hypothesis during the recorded run.Cursor CLI

    Cursor CLI asked for approval once and offered a "run everything" option, which was selected.

  • Observed: Observed by The Build Hypothesis during the recorded run.Claude Code

    Claude Code ran through without asking for further input during the run.

  • Agent claim: Reported by the agent in its own build report. Not independently verified.

    The agents split the same spec into very different requirement lists (73, 55 and 24 items), so the counts are not comparable.

  • Agent claim: Reported by the agent in its own build report. Not independently verified.

    All three ran into Cloudflare's production limit of 100,000 PBKDF2 iterations for password hashing, and each handled it differently.

No verdict yet.

A winner is only named once every build has been independently tested against the shared criteria, with the score components shown.

Episode

Not published yet

No episode link is available yet. It will appear here once the video is published.

Get notified on YouTube (opens in a new tab)

Explore more

Other experiments

EXP-002
PlannedCreative tool

AI Video Editor

A real browser video editor with a multitrack timeline, AI captions, plain-English edits and a genuine MP4 export.

  • CCClaude Code
  • CXOpenAI Codex
  • CUCursor CLI
Time budget
8h / agent
Spec version
Spec v1.1
Runs
Runs not started
EXP-003
PlannedGame

3D Basketball Game

Five-on-five basketball in the browser, with real ball physics, keyboard control and an AI opponent.

  • CCClaude Code
  • CXOpenAI Codex
  • CUCursor CLI
Time budget
8h / agent
Spec version
Spec v1.0
Runs
Runs not started
EXP-004
PlannedGame

Project Bulletstorm

A stationary 3D lane shooter where you steer an auto-firing squad, recruit soldiers and survive ten levels.

  • CCClaude Code
  • CXOpenAI Codex
  • CUCursor CLI
Time budget
8h / agent
Spec version
Spec v1.0
Runs
Runs not started